When designing clustered WebLogic deployments that use JMS it is usual to introduce load balancing into the JMS infrastructure so that incoming transaction arriving via JMS get distributed evenly across the servers in the cluster. The way that this is done in WebLogic is by creating a distributed destination with an individual physical queue in each member of the cluster. This allows the application components (e.g. EJB Message Driven Beans) to be configured with a single JNDI name so that the same application component can be deployed to every node in the cluster and will continue to work even if a cluster member goes down. Load balancing is enabled via the connection factory settings by specifying that the JMS connection factory should have load balancing enabled and (usually) server affinity disabled. This is usually a good thing.
For outbound messages (e.g. response messages from the same transactions) it is also normal to set up a distributed destination, again so that the application can be written with a single configured JNDI name which will work everywhere in the cluster. It is also possible to use a load balanced connection factory for the outbound messages. I can see no real advantages to using load balancing in this context. Gut feel and colleagues told me that it was a bad idea but until recently I could not point to any proven problems with this setup.
I have now seen an example of a real problem which seems to be happen when outbound load balancing is used…
First a little scene setting. One of the other advantages of clustering is that when we find ourselves facing one of those situations that should not happen and need to restart the application we can do so without making the whole system unavailable by doing a ‘rolling bounce’ in which the cluster members are bounced in turn so that there is never a time when none of them are available.
Recently we received reports of that one of our client systems was occasionally timing out waiting for JMS responses from us. This seemed to be happening in bursts at the same time as we were doing a rolling bounce to resolve an unrelated issue. Checking our database showed that we had processed the transaction and recorded a response message. Checking the logs, however, showed that there had been a problem…
[16/02/11 04:01:48:048 GMT] ABC_COMPONENT ERROR Exception Logger: Caught exception during processing void com.xyz.abc.common.servicelayer.SimpleJmsSender.sendMessage(String, Map)
org.springframework.jms.IllegalStateException: [JMSClientExceptions:055076]The session is closed; nested exception is weblogic.jms.common.AlreadyClosedException: [JMSClientExceptions:055076]The session is closed
at org.springframework.jms.support.JmsUtils.convertJmsAccessException(JmsUtils.java:252)
at org.springframework.jms.support.JmsAccessor.convertJmsAccessException(JmsAccessor.java:172)
Collecting up all of the logs from the cluster members showed that these exceptions always happened when one of the other managed servers in the cluster was being bounced. I concluded from this that the outbound messages were being round-robin load balanced across all of the managed servers and that when one server was bounced it caused errors to the applications running on the remaining servers.
Now I think that WebLogic JMS should handle this rather better. I also know that the application’s error handling needs to be improved so that it doesn’t commit the database changes if the JMS response message transmission fails. Nevertheless it does highlight a scenario in which outbound load balancing introduces the possibility of a problem which would not be there if the outbound messages were sent without load balancing.
Conclusion: when using a distributed JMS destination to send outbound messages from a cluster you should use a connection factory with load balancing disabled and server affinity enabled.
Before closing it’s worth observing that outbound load balancing is something that I’ve seen configured on several WebLogic projects and thinking about why this is so…
Most of the projects that I’ve seen have begun life in a non-clustered setup. In such a setup it is usual to use a single JMS connection factory for both inbound and outbound messages. Unless there is some special tuning required then there is no real problem with such a setup. When clustering is introduced the team reads the manual, learns about distributed JMS destinations and creates them. They introduce inbound load balancing by reconfiguring their existing connection factory but stick with the single connection factory setup and overlook the fact that they have also implicitly introduced outbound load balancing.
Showing posts with label Reliability. Show all posts
Showing posts with label Reliability. Show all posts
Monday, 28 February 2011

Friday, 30 April 2010
Memory Leak Case Studies Part 3
The third and final installment (probably) in the series on memory leak case studies describing real memory leaks and similar Java heap stress conditions that I’ve seen myself and how they were tracked down and fixed.
This particular issue took a long time to resolve because it wasn't in code that we controlled and tracking down information about the problem proved very difficult.
weblogic.jms.dd.DDMember
After clustering our WebLogic 9.2 servers we found that the managed servers would run into major heap stress and sometimes go offline on some of our test environments. Unfortunately the problem was not easily reproducible and didn't seem to happen on environments that we could easily mess with.
A heap histogram from jmap looked like...
255076744 2969890 char[]
71728608 2988692 java.lang.String
34196104 287745 * ConstMethodKlass
30874880 385936 weblogic.jms.dd.DDMember
20721808 287745 * MethodKlass
18528600 772025 weblogic.jms.common.JMSID
18527736 771989 weblogic.messaging.dispatcher.DispatcherId
15454080 386352 weblogic.cluster.BasicServiceOffer
14538712 24883 * ConstantPoolKlass
12604000 259169 * SymbolKlass
10601304 24883 * InstanceKlassKlass
9763528 29806 byte[]
9262056 385919 weblogic.jms.dd.DDMemberStatusSharer
7797008 18852 * ConstantPoolCacheKlass
6628720 118370 org.codehaus.groovy.runtime.metaclass.MetaMethodIndex$Entry
6175856 385991 weblogic.jms.common.JMSServerId
We also got some heap dumps, but it was pretty obvious from the outset that the memory leak related to WebLogic internal classes. We checked and ruled out the obvious things that were under our control (e.g. too many messages building up in JMS queues). We also googled for the problem and searched Oracle Metalink but didn't turn up any useful advice. The only option left was to raise a case with Oracle, which is what we did.
Oracle responded to the case with the advice to increase the heap size to 2Gb on all servers. We did this and our test environments became more stable. the problem did not recur in test so eventually the clustering changes made it into production.
I'm sure that you can guess where this story is going ...
After clustering went live we found that the managed servers would stay up for roughly 24 hours before running into problems and needing to be restarted. The initial symptoms that were noticed were BEA-000115 messages (which say that a multicast packet was lost) and BEA-000511 messages (which say unsolicited reply), along with high CPU utilisation.
Naturally a new Oracle case was opened. Initially it was thought that the problem was being caused by a poor choice of multicast addresses. Another week went by while the system was reconfigured with what seemed to be better multicast addresses, but still the problem remained.
I did some analysis of the logs using Splunk (a great tool BTW, but that's another story) and found that the messages seemed to appear in bursts starting an hour or two before the CPU utilisation became really high. Here is a Splunk graph showing the occurrences of one of the message types.

I'd also asked for jstat data which confirmed that the servers were filling up their heaps. I also found that the WebLogic logs contained some BEA-310002 messages that shed some light on the behaviour of the problem over a longer period. I used splunk to produce a graph from these:-

This graph seemed to indicate that the problem was related to the uptime of the servers rather than the amount of work they were doing (the behaviour was the same on a Sunday as on a working day). This prompted an idea for improving the stability of our system - avoid restarting all of the servers at the same time and then there would be a good chance that they wouldn't all fail at the same time. Unfortunately the change control procedures for the production system pretty much ruled this out, so we were stuck with restarting the servers each time they ran into trouble.
Finally Oracle support came back to us with the advice that this was a known bug in WebLogic for which a patch was available - 'BUG 8160383 - [CR368242]'. We applied this fix, tested it and put it into production and found that the problem was solved.
So I then wondered why we hadn't found the cause sooner. The Oracle support people said that the description of the patch said that it fixes "leaking objects weblogic.jms.dd.DDMember". I went back into Metalink and looked up the information relating to the bug and the patch and found that it contained mostly blank text and no mention at all of 'DDMember' which is probably why I couldn't find it. I wonder whether some of the information was perhaps lost in the transition from WebLogic's bug database into Metalink. Clearly the Oracle support people have another source of information available to them.
This particular issue took a long time to resolve because it wasn't in code that we controlled and tracking down information about the problem proved very difficult.
weblogic.jms.dd.DDMember
After clustering our WebLogic 9.2 servers we found that the managed servers would run into major heap stress and sometimes go offline on some of our test environments. Unfortunately the problem was not easily reproducible and didn't seem to happen on environments that we could easily mess with.
A heap histogram from jmap looked like...
255076744 2969890 char[]
71728608 2988692 java.lang.String
34196104 287745 * ConstMethodKlass
30874880 385936 weblogic.jms.dd.DDMember
20721808 287745 * MethodKlass
18528600 772025 weblogic.jms.common.JMSID
18527736 771989 weblogic.messaging.dispatcher.DispatcherId
15454080 386352 weblogic.cluster.BasicServiceOffer
14538712 24883 * ConstantPoolKlass
12604000 259169 * SymbolKlass
10601304 24883 * InstanceKlassKlass
9763528 29806 byte[]
9262056 385919 weblogic.jms.dd.DDMemberStatusSharer
7797008 18852 * ConstantPoolCacheKlass
6628720 118370 org.codehaus.groovy.runtime.metaclass.MetaMethodIndex$Entry
6175856 385991 weblogic.jms.common.JMSServerId
We also got some heap dumps, but it was pretty obvious from the outset that the memory leak related to WebLogic internal classes. We checked and ruled out the obvious things that were under our control (e.g. too many messages building up in JMS queues). We also googled for the problem and searched Oracle Metalink but didn't turn up any useful advice. The only option left was to raise a case with Oracle, which is what we did.
Oracle responded to the case with the advice to increase the heap size to 2Gb on all servers. We did this and our test environments became more stable. the problem did not recur in test so eventually the clustering changes made it into production.
I'm sure that you can guess where this story is going ...
After clustering went live we found that the managed servers would stay up for roughly 24 hours before running into problems and needing to be restarted. The initial symptoms that were noticed were BEA-000115 messages (which say that a multicast packet was lost) and BEA-000511 messages (which say unsolicited reply), along with high CPU utilisation.
Naturally a new Oracle case was opened. Initially it was thought that the problem was being caused by a poor choice of multicast addresses. Another week went by while the system was reconfigured with what seemed to be better multicast addresses, but still the problem remained.
I did some analysis of the logs using Splunk (a great tool BTW, but that's another story) and found that the messages seemed to appear in bursts starting an hour or two before the CPU utilisation became really high. Here is a Splunk graph showing the occurrences of one of the message types.

I'd also asked for jstat data which confirmed that the servers were filling up their heaps. I also found that the WebLogic logs contained some BEA-310002 messages that shed some light on the behaviour of the problem over a longer period. I used splunk to produce a graph from these:-
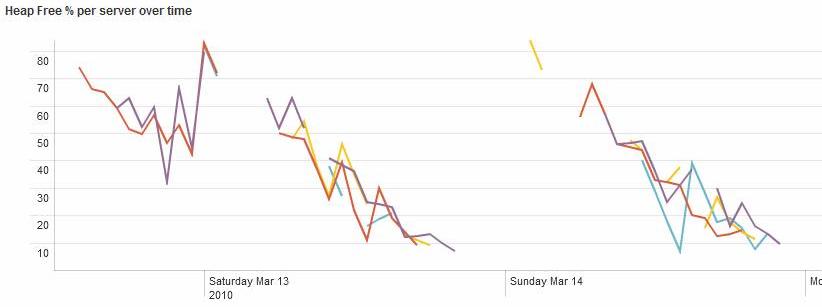
This graph seemed to indicate that the problem was related to the uptime of the servers rather than the amount of work they were doing (the behaviour was the same on a Sunday as on a working day). This prompted an idea for improving the stability of our system - avoid restarting all of the servers at the same time and then there would be a good chance that they wouldn't all fail at the same time. Unfortunately the change control procedures for the production system pretty much ruled this out, so we were stuck with restarting the servers each time they ran into trouble.
Finally Oracle support came back to us with the advice that this was a known bug in WebLogic for which a patch was available - 'BUG 8160383 - [CR368242]'. We applied this fix, tested it and put it into production and found that the problem was solved.
So I then wondered why we hadn't found the cause sooner. The Oracle support people said that the description of the patch said that it fixes "leaking objects weblogic.jms.dd.DDMember". I went back into Metalink and looked up the information relating to the bug and the patch and found that it contained mostly blank text and no mention at all of 'DDMember' which is probably why I couldn't find it. I wonder whether some of the information was perhaps lost in the transition from WebLogic's bug database into Metalink. Clearly the Oracle support people have another source of information available to them.
Tuesday, 12 February 2008
An Accident Waiting to Happen
My client is in the process of rolling out a multi-tier J2EE application which has been in development for a couple of years. A couple of weeks ago, it started to run into mysterious 'hanging' states in production. Many crisis meetings took place, DBAs and app experts were engaged, actions happened and everybody had a generally stressful time without quite getting to the bottom of the issue.
In a quieter moment, going over emails from the DBAs, thread dumps and source code, I spotted a problem. A Java class was querying Oracle for the next value of a sequence, putting it in an instance variable and then using it later to do an insert or an update. Nothing too scary on the face of it... until you realise that an instance of this class was being held in an instance variable in another class, and that class was a WebLogic web service skeleton.
Now the WebLogic manual is very clear that you must write thread-safe code for your skeleton classes because the will use a single instance of the skeleton to service all client requests. End result: a single instance of our class is running in multiple threads and the database keys are getting mixed up between threads, resulting in multiple threads trying to lock the same database row and causing the app to hang.
So should we blame the developers of this class?, well maybe, but bear in mind that the class in question is not itself a web service skeleton - it just happens to be used by one. Maybe we should blame the developer of the skeleton?, well that may be closer to the mark, but I have another option - maybe we should blame the developer of the web service framework!
My question is: is this rule reasonable? The expectation nowadays is that developers will quickly be up to speed with new technologies and that businesses will want to take advantage of them quickly. We cant expect development shops to be peopled entirely by seasoned professionals, so surely the burden should fall on the developers of frameworks to implement default behaviours which are safe.
Having hit this issue, I cross-checked what does in the same situation. At first, I couldn't find any definitive statement in the manual on the subject, so I ran a service in the debugger and found that it created lots of instances of my skeleton as calls arrived. I eventually found that the bahaviour is configurable via the 'scope' property in the web service deployment descriptor (). The default seems to be 'session' - i.e. an instance of the skeleton is created for each client that connects. Not 100% safe, not 100% optimal performance-wise, but probably safe enough for most situations.
My client now needs to either check all web-service related code for thread safety or switch to another web service framework that at least makes this behaviour configurable... and then roll out the change into production and retro-fit the two releases which are still in the pipeline. This is not going to be a painless process.
I will just be thankful that I wasn't around when the framework was chosen or when the code in question was written - would I have spotted this accident before it happened?
Subscribe to:
Posts (Atom)

 Posts


